Your first-party data, made intelligent

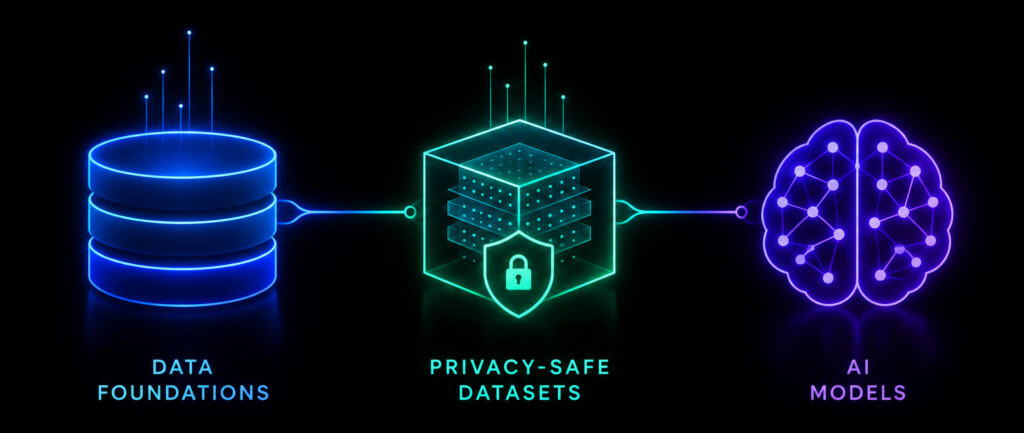
Little Moon Media builds the data foundations, privacy-safe datasets and AI models that turn a company’s own customer data into audiences, predictions and decisions. US-based. B2B only.

the problem

Most companies own more data than they can use

Customer records sit in a CRM. Behavior sits in analytics. Transactions sit in a back-office system.

Each one is partial, inconsistent and, in its raw form, too sensitive to move freely between teams and partners.

The result is familiar: audiences built on guesswork, media spent on the wrong people, AI projects that stall because the data underneath them was never ready.

What we build

From raw data to decisions, in five steps

We work end to end, or on the single step you need.

First-Party Data Foundation

We collect, unify and govern your customer data into one reliable source of truth.
Data Anonymization & Privacy Engineering

We make that data safe to use and share: pseudonymization, hashing, aggregation, clean-room-ready structures.
Dataset Engineering & Enrichment

We turn clean data into modeling-ready datasets, enriched with large-scale US data sources.
AI Audience Modeling

We model segments, propensity and lookalikes from your own data, not from generic third-party profiles.
AI Models & Decision Tools

We deliver the models, dashboards and tools your teams use every day.
Why Little Moon

Why companies work with us

First-party first. Your data stays yours. We make it work harder instead of renting someone else’s.

Privacy by construction. Anonymization is designed in from the first pipeline, not added at the end.

US-grade AI. We work where AI development happens, with access to large-scale data sources and methods before they reach the mainstream.

Built, not bought. Custom models and platforms shaped around your data and your decisions.

Data you can actually use

Anonymization is not a compliance checkbox: it is what allows data to move between teams, partners and platforms without exposing a single person.

We pseudonymize identifiers, aggregate where detail is not needed, and structure datasets so they can be matched in clean rooms without ever sharing raw records.

Results

Three result cards, each linking to its full page. See the case study section for copy.

Three steps to the first model

Assess

Two to three weeks. We map your data sources, quality and gaps, and agree on the KPI that matters.
Pilot

Six to eight weeks. We build the pipeline and the first model on one use case, and measure it.
Scale

We extend to further use cases, automate the pipeline and hand your teams the tools.

Start with your own data

Tell us what data you hold and what decision you want to improve. We will tell you what is possible.